
Sitemap
A list of all the posts and pages found on the site. For you robots out there, there is an XML version available for digesting as well.
Pages
Posts
portfolio
publications
Habibi: Laying the Open-Source Foundation of Unified-Dialectal Arabic Speech Synthesis
发表于Published in arXiv preprint arXiv:2601.13802, 2026
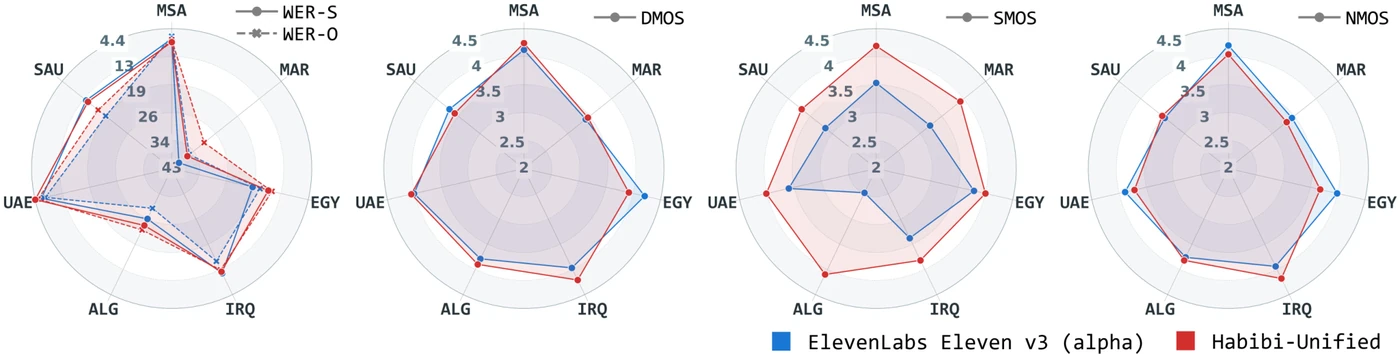
Habibi is a unified-dialectal Arabic TTS framework covering 12+ regional dialects. Our unified model matches or surpasses per-dialect specialized models and is highly competitive with ElevenLabs Eleven v3 (alpha).

推荐引用:Recommended citation: Y. Chen, J. Liu, Y. Tu, Z. Niu, Y. Liang, C. Qiang, C. Zhang, K. Yu, X. Chen. (2026). "Habibi: Laying the Open-Source Foundation of Unified-Dialectal Arabic Speech Synthesis." arXiv preprint arXiv:2601.13802.
下载论文Download Paper
VIBEVOICE-ASR Technical Report
发表于Published in arXiv preprint arXiv:2601.18184, 2026
VibeVoice-ASR is a general-purpose speech understanding framework that supports single-pass processing for up to 60 minutes of audio, unifying ASR, Speaker Diarization, and Timestamping into a single end-to-end generation task. It supports over 50 languages and natively handles code-switching.


推荐引用:Recommended citation: Z. Peng, J. Yu, Y. Chang, Z. Wang, L. Dong, Y. Hao, Y. Tu, C. Yang, W. Wang, et al. (2026). "VIBEVOICE-ASR Technical Report." arXiv preprint arXiv:2601.18184.
下载论文Download Paper
OpenSTBench: Beyond Semantic Evaluation for Speech Translation
发表于Published in arXiv preprint arXiv:2605.30792, 2026
OpenSTBench is a unified multidimensional evaluation framework for speech translation, covering S2TT and S2ST systems in both offline and streaming settings. It jointly measures translation quality, speech quality, speaker preservation, emotion and paralinguistic fidelity, temporal consistency, and latency.


推荐引用:Recommended citation: Y. An, Y. Zhao, Y. Zhang, Q. Zheng, Y. Tu, K. Deng, K. Yu, and X. Chen. (2026). "OpenSTBench: Beyond Semantic Evaluation for Speech Translation." arXiv preprint arXiv:2605.30792.
下载论文Download Paper
GigaSpeechBench: A Real-World Multilingual Speech-to-Text Benchmark
发表于Published in arXiv preprint arXiv:2606.28884, 2026
First-author work. GigaSpeechBench is a 680-hour, human-annotated, real-world ASR & AST benchmark covering low-resource languages, Chinese dialects, English accents, vertical-domain terminology, and speech from older adults and children.


推荐引用:Recommended citation: Y. Tu, Y. Yang, T. Wang, Y. Zhu, G. Lin, M. Shao, H. Wang, J. Liu, Y. Fu, et al. (2026). "GigaSpeechBench: A Real-World Multilingual Speech-to-Text Benchmark." arXiv preprint arXiv:2606.28884.
下载论文Download Paper
VibeVoice-ASR-BitNet Technical Report
发表于Published in arXiv preprint arXiv:2607.21075, 2026
VibeVoice-ASR-BitNet compresses VibeVoice-ASR for real-time multilingual recognition on edge CPUs through heterogeneous quantization, custom SIMD kernels, and fused operators. It is 1.6-2.3x faster than Whisper.cpp at comparable model sizes.


推荐引用:Recommended citation: S. Xu, T. Song, S. Huang, Z. Peng, Y. Xia, Y. Tu, X. Huang, X. Wu, W. Wang, Y. Chang, J. Yu, L. Dong, and F. Wei. (2026). "VibeVoice-ASR-BitNet Technical Report." arXiv preprint arXiv:2607.21075.
下载论文Download Paper
VibeVoice-ASR-Streaming Technical Report
发表于Published in arXiv preprint arXiv:2609.02812, 2026
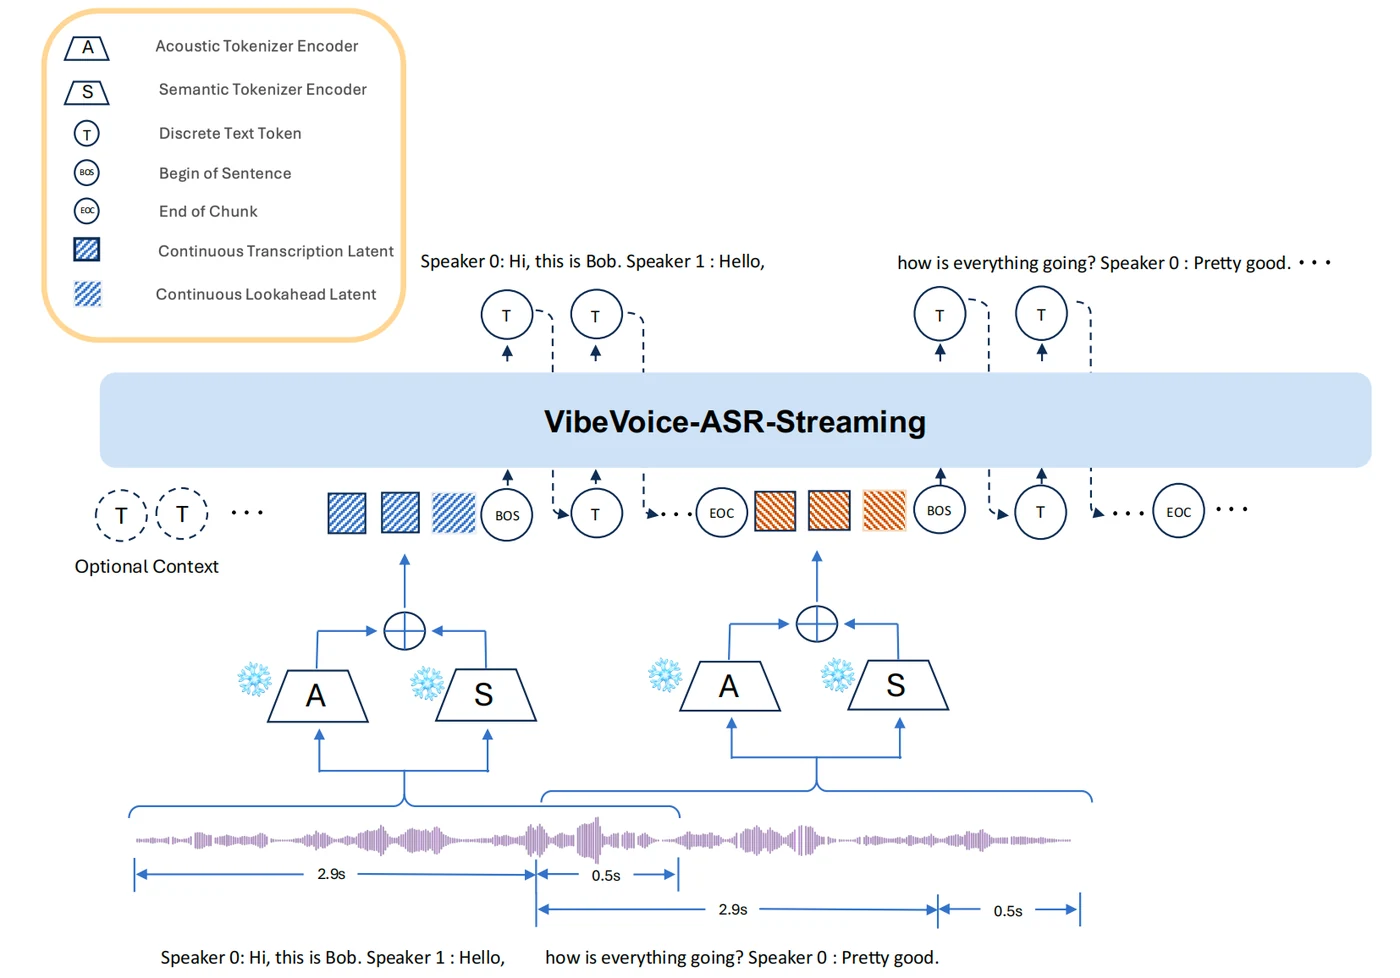
VibeVoice-ASR-Streaming is one of the first LLM-based end-to-end approaches to streaming speaker-attributed ASR. By interleaving fixed-size audio chunks, a small amount of lookahead audio, and previous text, it produces “who said what” as speech arrives, with no separate diarization stage.
推荐引用:Recommended citation: Y. Tu, Z. Peng, J. Yu, L. Dong, S. Xu, Y. Chang, W. Wang, Z. Wang, Z. Wang, Y. Xia, J. Zhang, X. Chen, and F. Wei. (2026). "VibeVoice-ASR-Streaming Technical Report." arXiv preprint arXiv:2609.02812.
下载论文Download Paper